Which AI model searches the web better on a Japan factory-location question?
We gave 12 AI models the same question with web search on. This page measures how far each model searched and whether the pages it cited back what it wrote. It compares the models, not their advice.
As asked, word for word.
Give me the top 5 location where I can incorporate an entity in Japan as a food manufacturer. Consider the government subsidy as well.
Output condition
- Include fact links after the paragraph or sentence
The question needs current, local sources: subsidy caps, rates, and deadlines that prefectures and cities publish in Japanese. It tests whether a model finds those pages and quotes them correctly.
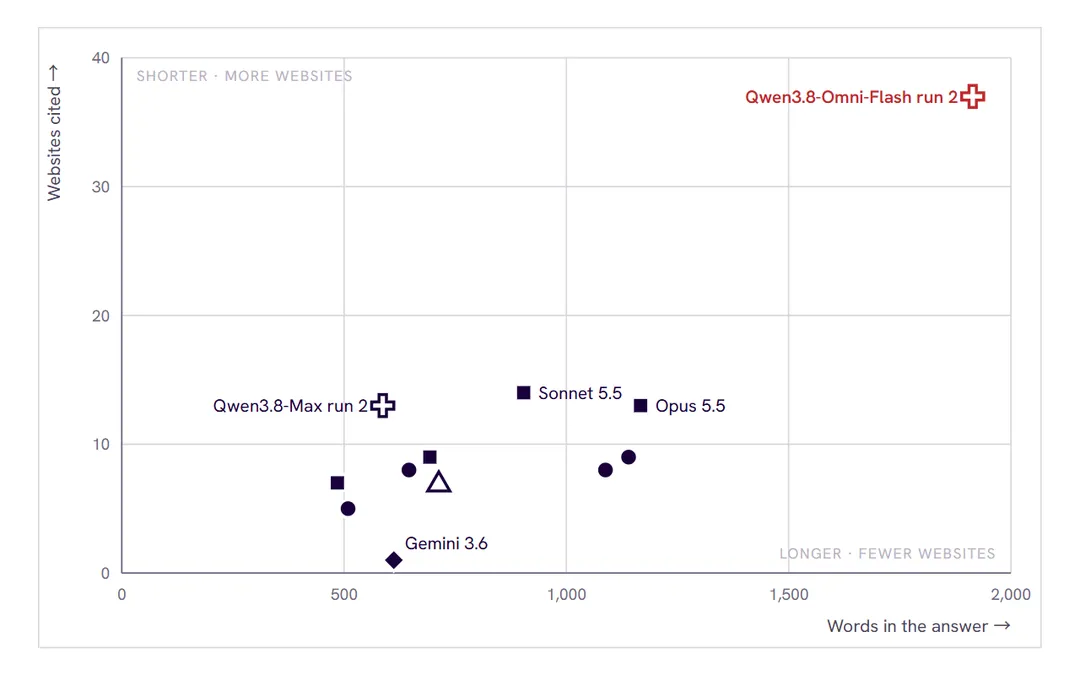
Which model researched further?
Show as a table
| Answer | Words | Websites cited |
|---|
More websites means the model looked further. It does not mean the answer is right. The next chart checks that.
Which answer holds up as written?
We opened every cited link and compared the page with the passage that cites it. A passage is backed when every figure, name, date, and condition in it is on the page.
What the check caught
- Grok 4.7: a factor of ten.It puts combined Fukui support at ¥5 to 8 billion. Its own source lists 5〜8億円, which is ¥0.5 to 0.8 billion.
- Opus 5.5: a closing date.It says the SME growth subsidy round closes 29 October. The listing it cites gives 12 November.
- Qwen3.8-Max: AI citing AI.Four of its six cited passages rest on other AI answers in this library. Its Shizuoka ranking contradicts the report it cites.
- Gemini 3.6: figures without a page.Four of five passages carry caps or rates that its JETRO links do not show.
What this means when you pick a model for research.
Breadth is not accuracy.
Qwen3.8-Omni-Flash cited 37 websites, the most, but in a list at the end. No claim in it can be traced to one link. Qwen3.8-Max cited 13 websites, and four of its six passages lean on other AI answers.
Ask for the link beside each claim.
Ten answers put the link next to the sentence. That is what made them checkable: 65 of their 95 cited passages hold up in full.
Check the number, not just the program.
Most misses were one figure. The subsidy exists, but the cap, the rate, or the date is not on the page. Open the page before a number goes into your plan.
Links age fast.
Three weeks after the answers were saved, seven cited pages no longer opened. Subsidy rounds also open and close, so check the dates on the page itself.
Every answer, with its numbers.
| Model | Setting | Words | Websites | Passages checked | Backed | Partly | Not backed |
|---|---|---|---|---|---|---|---|
| Opus 5.5 | Medium | 1,167 | 13 | 19 | 13 | 4 | 2 |
| Sonnet 5.5 | Medium | 904 | 14 | 8 | 6 | 2 | 0 |
| GPT-6 Luna | Max | 509 | 5 | 7 | 5 | 2 | 0 |
| GPT-6.1 Sol | Max | 1,140 | 9 | 16 | 13 | 3 | 0 |
| GPT-6 Astra | Max | 1,088 | 8 | 14 | 11 | 3 | 0 |
| Gemini 3.6 | Thinking | 612 | 1 | 5 | 1 | 4 | 0 |
| Grok 4.7 | Fast | 744 | – | No links in the saved copy | |||
| Grok 4.7 | Fast | 713 | 7 | 9 | 5 | 2 | 2 |
| Qwen3.8-Max | Thinking | 545 | – | No links in the saved copy | |||
| Qwen3.8-Max | Thinking | 587 | 13 | 6 | 0 | 5 | 1 |
| Qwen3.7-Plus | Fast | 616 | – | No links in the saved copy | |||
| Qwen3.7-Plus | Fast | 985 | – | No links in the saved copy | |||
| Qwen3.8-Omni-Flash | Thinking | 1,174 | – | No links in the saved copy | |||
| Qwen3.8-Omni-Flash | Thinking | 1,914 | 37 | 72 | 65 | 1 | 6 |
| Haiku 5.5 | Medium | 485 | 7 | 6 | 5 | 1 | 0 |
| Haiku 5.5 | Extra | 693 | 9 | 7 | 5 | 1 | 1 |
| GPT-6 Sol | Max | 646 | 8 | 7 | 6 | 1 | 0 |
More model comparisons
- Model comparisonWhich companies in Japan are most similar to KALDI Coffee Farm?
- Model comparisonTop 5 crowdfunding channels in Japan for overseas food providers: 6–12 month total project costs
- Model comparisonJapanese daily food demand and lasting consumption cases
- Model comparisonWhat Japanese food buyers need