Which AI model searches the web better on a Japan crowdfunding cost question?
We asked nine AI models the same question and kept one answer from each. Web search is recorded as on for eight of the nine. The record for Grok 4.7 does not say. This page counts the websites each answer cites. It does not open the links, so it cannot say whether the pages back what the answers wrote. It compares the models, not their advice.
As asked, word for word.
What are the top 5 crowd funding channel for overseas food providers in Japan.
We have limited budget, but we want to do more than testing.
My goal here is not to compare superficial price and functions, but I want to compare the total cost of 6-12 months project including creatives, ads, and commissions to the channels if exists.
Output condition
- Include fact links after the paragraph or sentence
The question asks for the total cost of a 6 to 12 month project, including creatives, ads, and commissions, not the headline fee. Platform fees sit on Japanese pages and change by plan, and few sources publish creative and ad costs. It tests whether a model finds the fee pages and says where its other numbers come from.
Which model researched further?
Show as a table
| Answer | Words | Websites cited |
|---|
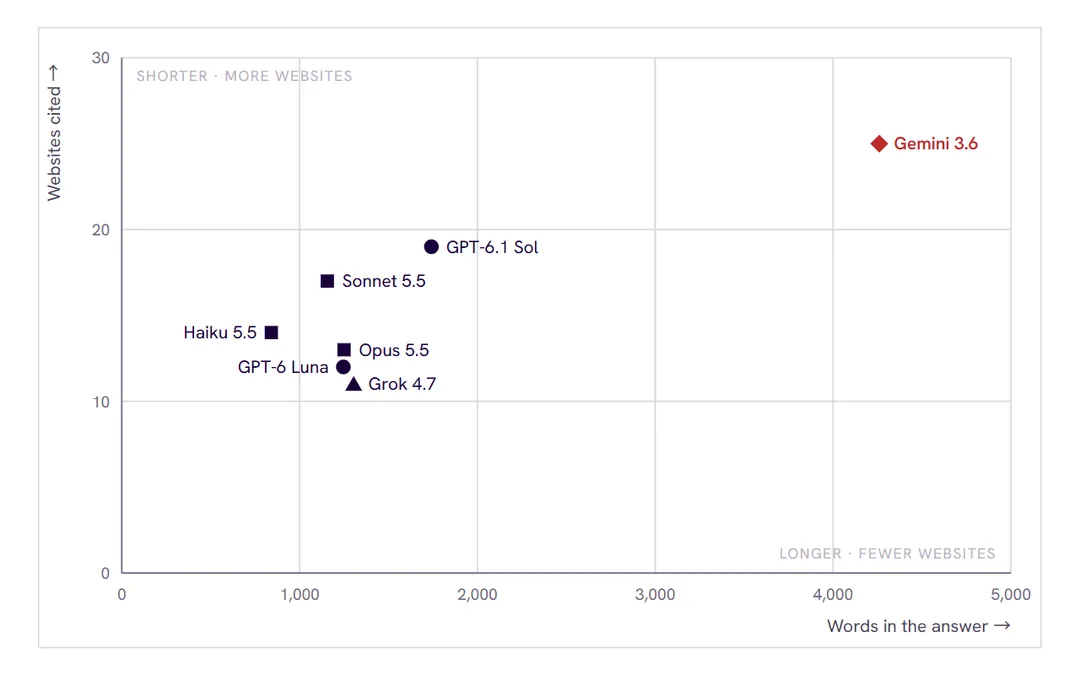
More websites means the model looked further. It does not mean the answer is right. That needs the link check below, which has not run for this question.
Do the cited pages back what the models wrote? Not checked yet.
In a checked comparison, we open every cited link and compare the page with the passage that cites it. For this question that has not happened. The numbers below say how much there is to check.
Cited links · one square per link, none opened yet
Until then, treat every figure in these answers as a lead, not a fact. Open the page before a number goes into your plan. To see what a finished check looks like, read the comparison How effective are interpreters and translation tools at trade-show booths in Japan?.
What this means when you pick a model for research.
The shortlists overlap.
Makuake and CAMPFIRE are in all nine lists of five channels. Kibidango and GREEN FUNDING are in eight, and READYFOR is in six. Kickstarter Japan is in two. Indiegogo Japan, machi-ya, and Saki ni Tabetai are each in one.
The cost totals are not on one scale.
The question asks for the total cost of a 6 to 12 month project. Each answer builds that total on its own assumed raise. GPT-6 Luna, GPT-6.1 Sol, Sonnet 5.5, and Haiku 5.5 assume ¥3 million. Opus 5.5 assumes two campaigns of ¥3 million each. Gemini 3.6 and Grok 4.7 assume ¥5 million, and Qwen3.8-Max assumes ¥10 million. Qwen3.8-Omni-Flash compares channels at ¥5 million and sums its closing budget on a raise of ¥3 to 5 million. Sonnet 5.5, Haiku 5.5, and Opus 5.5 label their cost tables as their own estimates.
Two answers give no links.
Qwen3.8-Max names its sources in brackets, for example 'gourmetpro.co, 2024-08-04', and lists five platform addresses inside a code block. Three of its bracketed citations name aireportlibrary.com, the library that stores these answers. Qwen3.8-Omni-Flash gives no link and no list of sources.
The longest answer also searched the widest.
Gemini 3.6 wrote 4,260 words, more than twice the next longest answer (GPT-6.1 Sol, 1,741 words), and cites 25 websites to Sol's 19. It cites by number and puts a list of titles and addresses at the end.
Every answer, with its numbers.
| Model | Setting | Asked | Words | Websites | Links |
|---|---|---|---|---|---|
| Opus 5.5 | Medium | 8 Oct 2026 | 1,250 | 13 | 13 |
| Sonnet 5.5 | Medium | 8 Oct 2026 | 1,156 | 17 | 17 |
| GPT-6 Luna | Max | 8 Oct 2026 | 1,246 | 12 | 13 |
| GPT-6.1 Sol | Max | 8 Oct 2026 | 1,741 | 19 | 27 |
| Gemini 3.6 | Thinking | 8 Oct 2026 | 4,260 | 25 | 30 |
| Grok 4.7 | Fast | 8 Oct 2026 | 1,304 | 11 | 16 |
| Qwen3.8-Max | Thinking | 8 Oct 2026 | 1,134 | – | |
| Qwen3.8-Omni-Flash | Thinking | 8 Oct 2026 | 1,661 | – | |
| Haiku 5.5 | Extra | 8 Oct 2026 | 841 | 14 | 16 |